What Are the Ethical and Legal Considerations of Web Scraping?
This article is for informational purposes only and does not constitute legal advice. Consult a qualified attorney for legal guidance specific to your situation.
Ethical web scraping means collecting only the public data you need, at a pace the site can carry, without deceiving anyone, and with respect for the privacy of the people in the data. The law sets the floor for that work. Ethics is the standard your program is actually judged by.
Every data team that runs extraction at scale eventually hits the same meeting. Legal asks whether the pipeline that feeds the analytics dashboard is going to get the company sued. Engineering says the data is public. Someone forwards a news story about a multi-million-euro fine, and the room goes quiet.
That meeting is the reason this guide exists. It starts with the ethics, then covers the legal floor underneath: no law bans web scraping as such, whether a given scrape is lawful turns on the data, how it is accessed and how it is used, and the landmark US cases mostly ended without merits rulings.
Quick Digest
- The ethics: Respect site owners and their servers, protect privacy, be transparent, collect only what you need, honor robots.txt, and never use deception to get past a barrier.
- The primary ethical concern: The privacy of the people in the data, who rarely know they were collected and carry the risk if the data is misused.
- The legal floor: No law bans web scraping as such. Whether a scrape is lawful turns on what data you take, how you access it, and how you use it.
- Case law: hiQ, Meta, X Corp and Ryanair ended in a consent judgment, a settlement or a waived or dropped appeal, not appellate merits rulings on scraping public pages.
- EU and UK: “It was public” is not a lawful basis for personal data, and regulators now weigh robots.txt when judging legitimate interest.
What are the ethical considerations of web scraping?
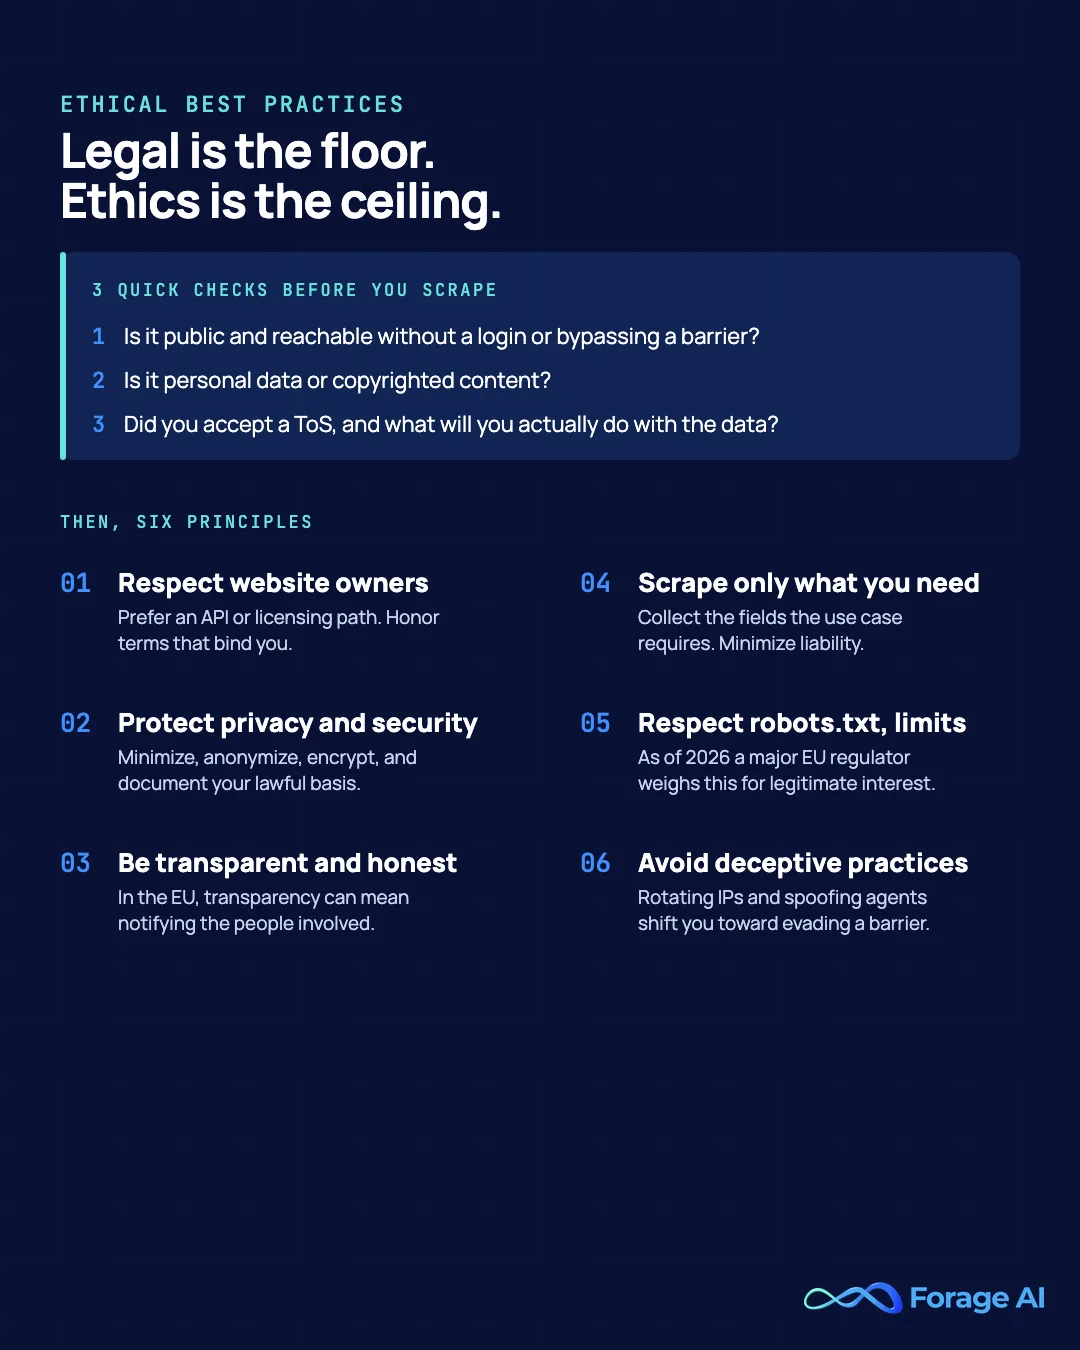
The ethical considerations of web scraping come down to six principles: respect the site owner and its servers, protect the privacy of the people in the data, be transparent about who you are, collect only what you need, honor robots.txt, and never use deception to get past a barrier.
Start with three quick checks before any new source. First, is the data public and reachable without logging in or bypassing a barrier? If you have to defeat authentication or a CAPTCHA, stop. Second, is it personal data or copyrighted content? If yes, you need a lawful basis or you need to limit yourself to facts. Third, did you accept a ToS, and what will you actually do with the data? Internal analytics is a different risk profile than resale or republication.
From there, the six principles do the rest of the work. They map to the failure modes we see most often in data reviews.
Respect site owners and their servers
Where a site offers an API or a data-licensing path, prefer it. Where the terms clearly prohibit collection and bind you, honor that. Seeking permission is slower, and it is the cheapest insurance against a contract claim. Credit the source when you use its content, and leave original expression with its owner.
Respect extends to the site’s servers, which is what the “web crawling” version of the question is about. A crawler that ignores load pushes its costs onto someone else. Read the Docs, the documentation host, reported in July 2024 that a single crawler downloaded “73 TB of zipped HTML files” in May 2024, “almost 10 TB in a single day,” costing the company “over $5,000 in bandwidth charges.” Throttle your requests, back off when a site slows down or starts returning errors, and skip pages you already hold.
Protect data privacy and security
If your scrape touches personal or sensitive data, treat it the way you would treat data you collected directly. Minimize what you keep, anonymize where you can, encrypt at rest and in transit, and document your lawful basis.
Be transparent and honest
Be straight about who you are, why you are collecting, and what you will do with the data. In practice that starts with an honest User-Agent string that names your crawler and gives the site a way to reach you. In the EU this is not optional courtesy. GDPR’s transparency duty can require notifying the people whose data you process, even when that data was already public.
Expert Insights
“Scraping violates the fairness principle because it is hidden and harmful. Because people are not notified when their data is scraped, they are often left unaware of data processing that exposes them to risk.” – Daniel J. Solove and Woodrow Hartzog, privacy-law professors, “The Great Scrape,” California Law Review, 2025
Collect only what you need
Collect the fields your use case actually requires and no more. Data minimization shrinks both your storage cost and your liability surface. It also keeps your request volume down, which is the same respect for the site’s servers by another route.
Respect the robots exclusion standard (robots.txt)
This used to be pure etiquette. As of January 2026 it is a signal EU regulators weigh: the French data protection authority (CNIL) treats ignoring a robots.txt or CAPTCHA objection as undermining your legitimate-interest basis. The European Data Protection Board’s draft Guidelines 03/2026 on web scraping, open for public consultation until 30 October 2026, go further: the absence of a robots.txt file “does not amount to consent” under GDPR. Honoring it does not make a scrape lawful, but ignoring it works against you.
Avoid deceptive scraping practices
Rotating IPs to dodge blocks, spoofing user agents, and mimicking human behavior to defeat detection move you from “collecting public data” toward “evading a barrier the site put up on purpose.” That shift is exactly the kind of conduct that turns a defensible scrape into a contested one.
Cambridge Analytica is often cited in scraping debates, but it was not a scraping case. According to the UK Information Commissioner’s Office (2018), a personality-quiz app collected the data through Facebook’s own platform API, which then let apps pull data on the people who installed them and, in some circumstances, on their friends. Many of the up to 87 million people affected never used the app. The failure was consent and purpose: data gathered for one reason and used for another, about people who were never asked. That applies to any collection method, scrapers included.
Quick Summary
Q: What are the ethical considerations of web scraping?
A: Run three checks first: is it public and barrier-free, is it personal or copyrighted, and what will you do with it. Then apply six principles: respect site owners and their servers, protect privacy and security, be transparent, collect only what you need, respect robots.txt, and avoid deceptive evasion. Cambridge Analytica shows what happens when consent and purpose are ignored.
Is web scraping ethical?
It can be. Whether it is depends less on the technique than on what you collect and what you do with it. Legal compliance is the floor, not the ceiling: a scrape can clear every statute that applies and still go past what the people in the data, or the site that hosts it, would reasonably accept.
The primary ethical concern is the privacy of the people in the data. They never agreed to be collected, they usually do not know it happened, and they carry the risk if the data leaks or is reused in ways they would object to. The second concern is the site owner, whose servers and content pay for your collection. That is why the six principles above go a step beyond the law, and why teams that follow them stay defensible as the law shifts.
What are the legal considerations for web scraping?
No law bans web scraping as such, in the US or the EU. Whether a given scrape is lawful turns on three factors, and since the landmark cases mostly ended without merits rulings, nobody can honestly give you a one-word verdict.
What you scrape. Public product prices and listings sit in a different legal category than personal data about identifiable people or content protected by copyright. The data type sets the baseline risk.
How you access it. Reaching a public page that anyone can load is one thing. Logging into an account, bypassing a paywall, or defeating a CAPTCHA is another, and that is where most of the serious US exposure lives: contract claims and the Computer Fraud and Abuse Act (CFAA).
What you do with it. Internal analytics, republishing whole articles, reselling a dataset, and training an AI model are not the same use. Copyright and contract claims tend to land on the downstream use, not the collection. We all know teams that treated “the data is public” as a complete answer and got a cease-and-desist anyway.
| Data type | What flips it illegal | US posture | EU / UK posture |
|---|---|---|---|
| Public, non-personal (prices, listings, specs) | Republishing protected expression; breaching an accepted ToS | Most permissive. Largely outside the CFAA and privacy law | Largely outside GDPR. Database rights can still apply to wholesale copying |
| Personal data (names, emails, profiles) | Processing without a lawful basis; no transparency to data subjects | CCPA applies; “publicly available” carve-out is narrow | GDPR applies even when the data is public. A lawful basis is required |
| Copyrighted content (articles, images, databases) | Copying and republishing substantial or whole works without permission | Copyright Act governs the use; facts and raw data are not copyrightable | Copyright plus EU database rights protect curated collections |
| Behind login or paywall | Bypassing authentication or a technical barrier to reach it | Classic CFAA and breach-of-contract trigger | Same, plus GDPR if the data is personal |
The line that trips most teams up is the jump from public to personal. In the EU, a name and job title from a public profile is still personal data.
“Found on the internet” does not mean “publicly available.” Under CCPA/CPRA (Cal. Civ. Code §1798.140), data restricted to a limited audience, such as a private or limited-access account, does not qualify for the publicly-available carve-out. Source: TrueVault / California AG, 2024.
Four bodies of law do most of the work in web-scraping disputes.
| Law | Where | What it actually governs |
|---|---|---|
| Terms of Service | Everywhere (contract) | A site’s terms may prohibit or conditionally allow scraping. They bind you only if you accepted them, for example by logging into an account. A logged-out visitor may not be bound at all. |
| Copyright | US, EU, UK | Copyright protects a site’s original content. Scraping and republishing substantial or whole works, such as full news articles, without permission can infringe. Facts and raw data themselves are generally not copyrightable. |
| CFAA | US | Prohibits accessing a computer “without authorization.” Van Buren (2021) read it as a gates-up-or-down test, but its footnote 8 left open whether contract or policy limits count. No appellate court has given a merits answer for scraping public pages. |
| GDPR / CCPA | EU+UK / California | Govern the processing of personal data. GDPR requires a lawful basis even for public personal data. CCPA grants California residents rights over their personal information. |
On copyright, you can scrape facts such as prices, scores and specifications. What you cannot do is republish a publisher’s original articles wholesale. On contract, the best-known district-court ruling for a scraper turned on logged-out access.
Expert Insights
“The Facebook and Instagram Terms do not bar logged-off scraping of public data; perforce it does not prohibit the sale of such public data.” – Judge Edward Chen, Meta Platforms v. Bright Data, 2024
Web scraping laws by country
The same scrape can be low-risk in the US and a regulatory problem in the EU, because each jurisdiction asks a different core question.
| Jurisdiction | Governing law | Core question | Public data posture |
|---|---|---|---|
| US | Contract, CFAA and state computer-crime laws, copyright, DMCA anti-circumvention | “Was access authorized?” | No federal statute bans scraping. The landmark cases ended without an appellate merits answer on public data. No comprehensive federal privacy law |
| EU | GDPR, database rights, AI Act | “Did you have a lawful basis to process personal data?” | “It was public” is not a lawful basis by itself. Regulators weigh robots.txt (CNIL 2026; EDPB draft guidelines, in consultation) |
| UK | UK GDPR, DPA 2018, Computer Misuse Act | Mirrors the EU on personal data | Near-identical to the EU. Personal data is the line |
Two EU dates matter for anyone scraping to build training sets. Obligations for general-purpose AI model providers under the EU AI Act have applied since 2 August 2025, and the Commission’s AI Office can enforce them, including fines, from 2 August 2026. The EU Data Act has applied since 12 September 2025, though it governs data from connected products rather than scraping. Both sit on top of GDPR, not in place of it.
€30.5 million fine imposed on Clearview AI for building a facial-recognition database from more than 30 billion photos scraped without consent. Source: Dutch Data Protection Authority (AP), 3 Sep 2024.
How the landmark scraping cases actually ended
These cases are often summarized as wins for scrapers. Read how each one actually ended and the picture changes.
| Case | What the court decided | How it ended | What it leaves open |
|---|---|---|---|
| hiQ Labs v. LinkedIn (9th Cir. 2022; N.D. Cal.) | The Ninth Circuit affirmed a preliminary injunction, finding hiQ raised “a serious question” on CFAA authorization for public pages. In October 2022 the district court held LinkedIn’s User Agreement prohibits scraping and fake accounts | Consent judgment, December 2022: $500,000 against hiQ, a stipulated CFAA count tied to fake accounts and password-protected pages, a permanent injunction, and destruction of the LinkedIn-derived data | No final merits ruling that scraping public pages is authorized access |
| Van Buren v. United States (US Supreme Court, 2021) | Read “exceeds authorized access” as a gates-up-or-down inquiry. An insider-credentials case, not a scraping case | Final decision | Footnote 8 expressly reserved whether limits in contracts or policies count |
| Meta Platforms v. Bright Data (N.D. Cal., 2024) | Summary judgment for Bright Data on Meta’s contract claim: logged-off scraping of public data was not “use” under Meta’s terms | February 2024 joint stipulation dismissed Meta’s remaining claim, and Meta waived its right to appeal | No appellate review |
| X Corp v. Bright Data (N.D. Cal., 2024 to 2025) | May 2024: claims dismissed on copyright-preemption reasoning. November 2024: the case was partly revived | Settled and dismissed with prejudice, June 2025. Terms undisclosed | No appellate ruling |
| Ryanair v. Booking.com (D. Del.; 3d Cir.) | July 2024 jury verdict found a CFAA violation with loss of exactly $5,000. In January 2025 the judge overturned it: provable loss was $2,457.72, below the $5,000 threshold | Ryanair’s appeal was voluntarily dismissed by agreement, August 2025 | No appellate ruling |
| Google v. SerpApi (N.D. Cal., filed December 2025) | DMCA anti-circumvention claims over SearchGuard. July 2026 split dismissal: claims over results with no copyrighted content dismissed without leave to amend; Knowledge Panel claims dismissed with leave | Google filed an amended complaint in August 2026. A motion to dismiss it is pending | Live: how far DMCA anti-circumvention reaches scraping |
None of these produced an appellate merits ruling on whether scraping public pages against a site’s terms is unauthorized access. For the full case-by-case map, see our guide to US web scraping laws.
None of these US cases touch GDPR. A scrape that survives a CFAA challenge can still be a €30 million problem in Europe if it sweeps up personal data without a lawful basis.
Ethical and legal web scraping checklist
Everything above turns into one list, organized the way a data team runs a pipeline: before, during and after collection.
Before you scrape.
- Check for an official API or data-licensing path first, and prefer it over scraping where one exists.
- Confirm the data is public and reachable without logging in or bypassing a technical barrier.
- Classify the data into one of the four buckets: public non-personal, personal, copyrighted, or behind-login.
- Read robots.txt and the ToS. Note whether the terms bind you, which generally means whether you have to log in.
- If the data is personal and any EU or UK data subjects are involved, document your lawful basis before you collect.
While you scrape.
- Honor robots.txt directives and the rate limits the site signals.
- Throttle request volume so you do not degrade the source site.
- Identify your crawler honestly in its User-Agent string.
- Collect only the fields your use case requires. Drop the rest at the point of collection.
- Do not spoof user agents or rotate IPs to defeat a barrier the site deliberately put up.
After collection, and governance.
- Encrypt personal data at rest and in transit, and restrict access to it.
- Set and enforce a retention period. Delete what you no longer need.
- Keep records of your lawful basis, your sources, and your collection decisions, so a review has something to read.
- Re-check the position when you change use, for example moving from internal analytics to resale or AI training, because the use is what copyright and contract claims attach to.
Most teams underestimate this part. Defensible extraction is not a one-time sign-off but ongoing work: tracking robots.txt as targets change it, re-scoping as sites restructure, and documenting decisions. That load is what a managed partner absorbs. Forage AI runs an end-to-end managed data pipeline built to each client’s fields. We agree sources, fields and handling rules with each client up front under contractual controls, we agree robots.txt and rate-limit handling with each client up front, and we handle selector drift and schema changes as part of the service.
If you are building the engineering side of this in code, the companion guide on web-scraping legal compliance covers the patterns, schemas, and checks at the implementation level. When the personal data arrives from a vendor or data broker rather than your own crawler, the downstream CCPA obligations are covered in our enterprise guide to CCPA implications for external data use.
Frequently asked questions
What are the ethical guidelines for web scraping?
Most teams work from six guidelines. Respect the site owner and its servers, and prefer an API or a licence where one exists. Protect the privacy and security of any personal data you touch. Be transparent about who you are, starting with an honest User-Agent. Collect only the fields you need. Honor robots.txt. And never use deception, such as spoofed identities or rotating IPs, to get past a barrier the site put up on purpose.
What are the ethical considerations of web crawling?
Crawling raises the same questions as scraping, plus one that grows with volume: load. Every request costs the site owner bandwidth and compute, and an aggressive crawler can slow a site down for its real users. Read the Docs reported one crawler pulling almost 10 TB from its servers in a single day in 2024. Ethical crawling means honoring robots.txt, throttling requests, backing off when a site slows down, and identifying your crawler honestly.
What are the most common ethical issues in web scraping?
Four come up most often. Collecting personal data about people who never agreed to it and do not know it happened. Overloading a site’s servers with uncontrolled request volume. Hiding who is collecting. And reusing data for a purpose its source never expected, such as republishing content wholesale. The €30.5 million Clearview AI fine in the Netherlands shows how far the first one can go.
Is web scraping legal in 2026?
No law bans web scraping as such, but no court has settled when scraping public pages is lawful. That depends on the data (personal or copyrighted), how you access it (logged in, or past a barrier), and how you use it. The best-known US cases, hiQ, Meta and X Corp, ended in a consent judgment, a waived appeal and a settlement, not binding appellate rulings. In the EU, personal data needs a lawful basis even when it is public.
Does robots.txt give me legal cover?
Honoring robots.txt does not by itself make a scrape legal, but ignoring it now works against you. As of January 2026, the French data protection authority treats a disregarded robots.txt scraping refusal as evidence against your GDPR legitimate-interest basis. Respecting it is a low-cost control that strengthens your position.
Is it legal to scrape personal data?
Generally not without a lawful basis. In the EU and UK, GDPR covers personal data even when it is public, so you need a basis such as legitimate interest and may owe transparency to the people involved. In the US, the CCPA “publicly available” carve-out is narrower than scrapers assume. If you ingest that data from a vendor instead, the same statute governs your downstream handling, the focus of our enterprise guide to CCPA implications for external data use.
Is it legal to scrape data behind a login or CAPTCHA?
This is the highest-risk category. Logging into an account usually binds you to the site’s terms, and bypassing authentication or a CAPTCHA is the classic trigger for CFAA and breach-of-contract claims in the US. The best-known ruling for a scraper, Meta v. Bright Data, turned on logged-off access to public data. hiQ’s consent judgment, by contrast, included a CFAA count tied to fake accounts and password-protected pages.
Can I get sued for scraping even if it is “legal”?
Yes. A scrape can avoid a CFAA claim and still draw a contract claim over a ToS you accepted, a copyright claim over republished content, or a privacy complaint over personal data. hiQ’s long fight with LinkedIn ended in a $500,000 consent judgment against hiQ that covered contract and CFAA counts. Legality is multi-axis, which is why the three-factor frame and the checklist matter.
Related articles
- Web Scraping Legal Compliance: Code Patterns and Checks. The engineering companion to this guide.
- How to Legally Extract Social Media Data at Scale. How the rules apply to platform data specifically.
- Web Data Extraction Services. What managed, governed extraction looks like in practice.
By Sneha