
Top 10 Web Scraping Service Companies: How to Choose the Right Provider for Your Business
Quick Digest
- Services vs tools: A scraping service owns the infrastructure, proxies, QA and delivery, while a tool leaves your team to build and maintain the workflow.
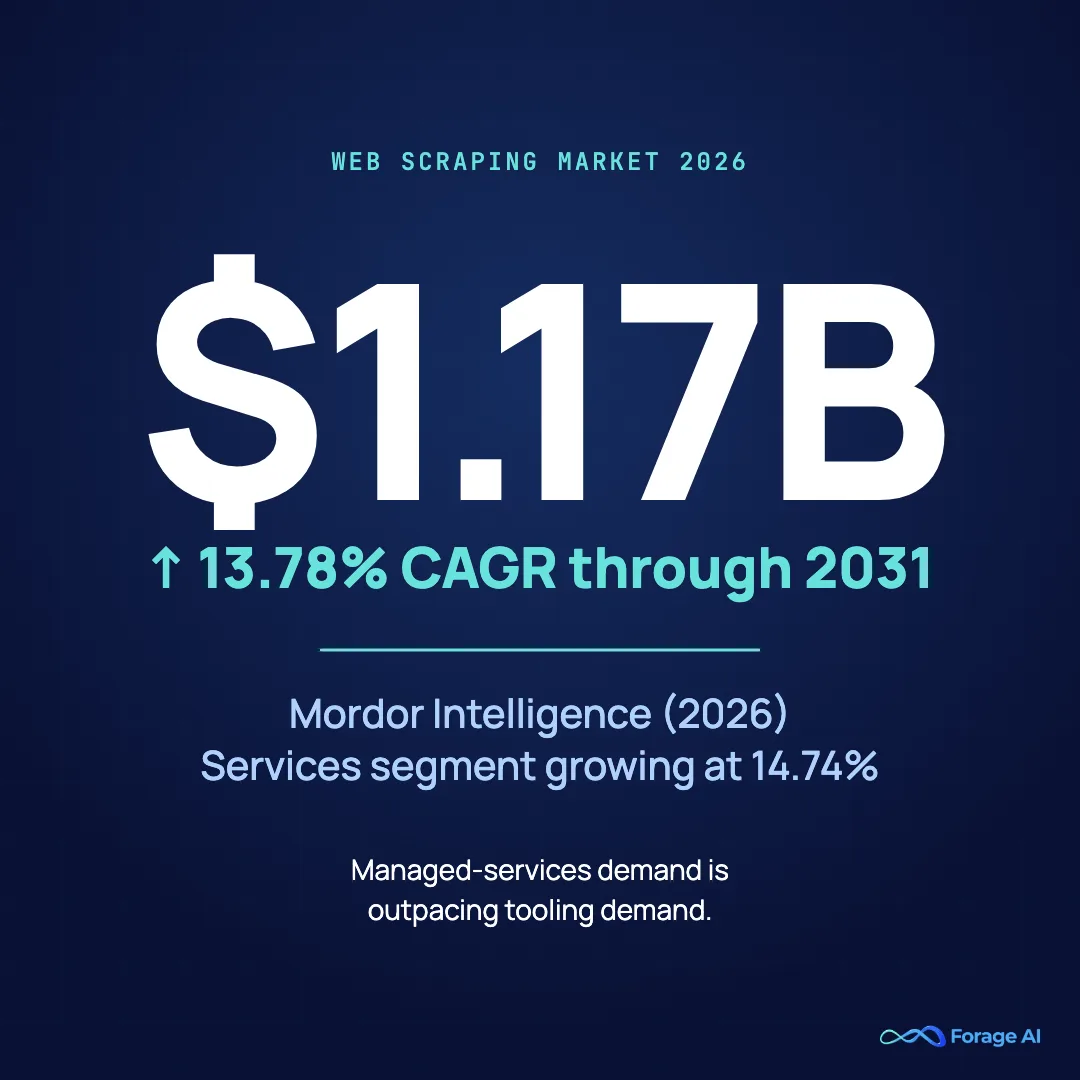
- Market shape: Mordor Intelligence puts the global web scraping market at USD 1.17 billion in 2026, with the services segment growing at 14.74% CAGR against the broader 13.78%.
- The shortlist: Forage AI, Bright Data, Oxylabs and Zyte rank highest on infrastructure stability, track record and enterprise support.
- Real cost: The cost drivers are proxy infrastructure, engineering response time when sites change, storage and post-processing, not the per-request price.
- Legal posture: In Meta Platforms v. Bright Data (N.D. Cal., 2024) the court found that Meta's terms did not reach logged-out scraping, which settled those contract terms rather than public-data scraping in general.
Introduction
Modern enterprises depend on web data for AI training, market research, competitive tracking, investment analysis, and product intelligence. The category is no longer niche: Mordor Intelligence values the global web scraping market at USD 1.17 billion in 2026, with a 13.78% CAGR projected through 2031. Yet collecting this data at scale still presents the same operational drag it always has: frequent website changes, anti-bot systems, and maintenance demands on engineering teams. Organizations must decide whether to develop in-house solutions or partner with a web scraping service for clean, reliable, ready-to-use data.
What This Guide Helps You Answer
- Which web scraping companies are the most reliable?
- What differentiates a basic scraping tool from an enterprise provider?
- How do you evaluate a vendor for accuracy, scale, and compliance?
- Which provider is the best match for specific use cases like finance, e-commerce, AI, SaaS, and market research?
Which Web Scraping Companies Are the Most Reliable?
Companies were evaluated based on infrastructure stability, experience, technical capabilities, compliance, security practices, and enterprise SLAs. The most reliable providers are Forage AI, Bright Data, Oxylabs, and Zyte, distinguished through proven uptime records, transparent reporting, and infrastructure supporting mission-critical enterprise data pipelines.
The web scraping services segment is growing at 14.74% CAGR vs the broader market’s 13.78% (Mordor Intelligence, 2026). Managed-services demand is outpacing tooling demand.
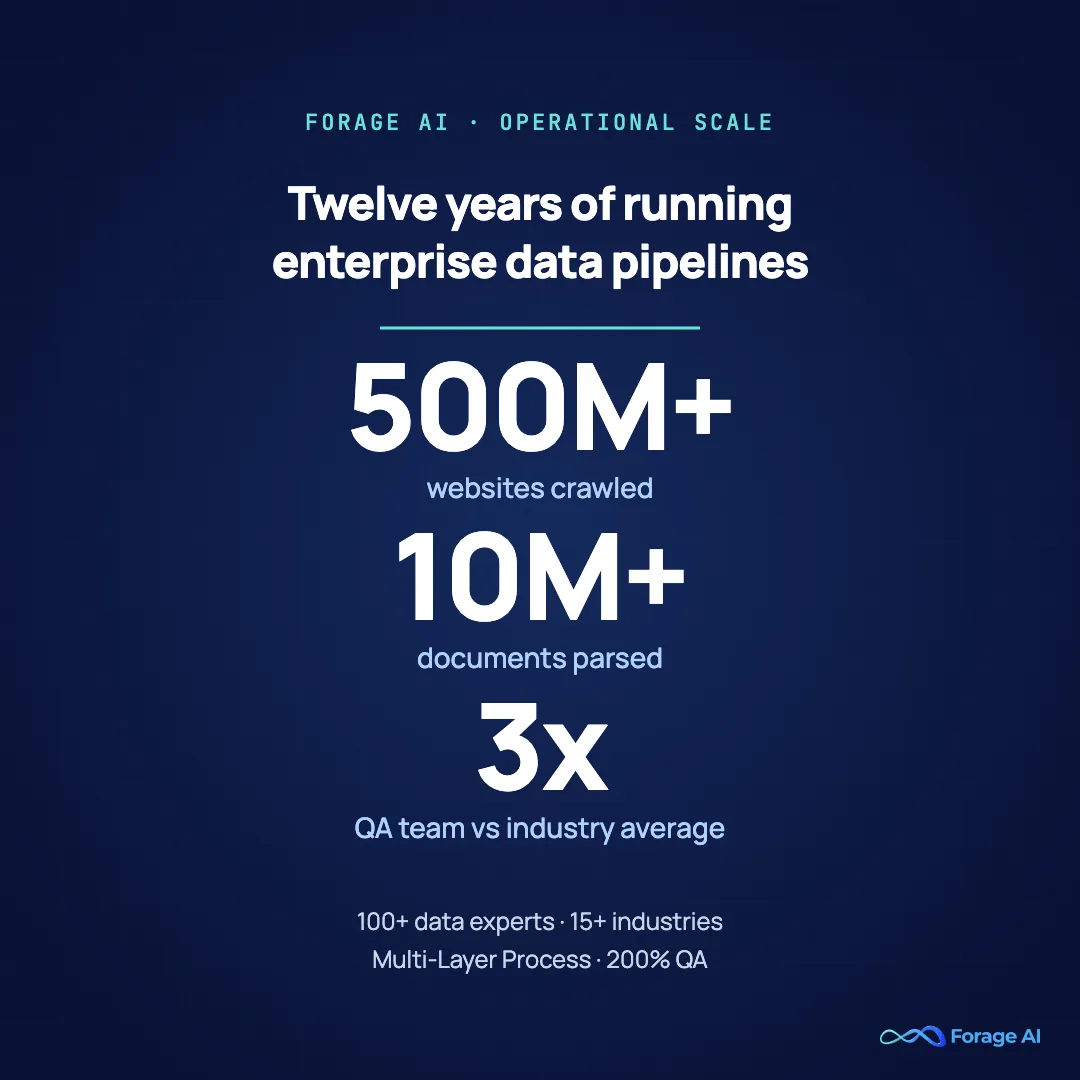
Forage AI has operated extraction pipelines for 12+ years across 500M+ websites and 10M+ documents, with a QA team three times the industry-average size relative to delivery.
Web Scraping Services vs. Web Scraping Tools
Web Scraping Services offer fully managed solutions where organizations define data requirements and providers handle infrastructure, proxy management, data cleaning, quality assurance, and scheduled delivery. This transforms data collection from an engineering project into a reliable business function with predictable costs and SLAs.
Web Scraping tools offer self-service platforms or APIs providing more control but requiring teams to build, maintain, and monitor scraping workflows. This approach demands significant engineering resources and ongoing attention to website changes and anti-bot measures.
Current Web Scraping Buying Trends
The structural shift in this category is no longer about HTML extraction. Mordor Intelligence (2026) reports the services segment growing at 14.74% CAGR, ahead of the broader 13.78% market CAGR, while price and competitive monitoring use cases are growing at 19.23% CAGR, the fastest of any application segment. The implication for buyers is direct: less appetite for DIY tooling, more demand for providers who deliver data that is structured, validated, and ready for machine learning pipelines, analytics platforms, and business applications.
How Do You Choose the Right Provider?
1. Why do you need this data, and how much of it?
Be clear about whether this is a one-time research project or continuous operational feed, how often updates are needed (real-time, daily, or weekly), and volume requirements (thousands of pages monthly or millions daily). Use case shapes everything from pricing to SLAs.
2. How complex are your target websites?
Some websites are simple HTML while others load heavily with JavaScript, use infinite scroll, feature dynamic content, or employ strict anti-bot protections. Match complexity to provider capabilities.
Expert Insights
Imperva, a Thales company, reported in its 2025 Bad Bot Report that "for the first time in a decade, automated traffic surpassed human activity, accounting for 51% of all web traffic in 2024," with malicious bots alone at 37%. That is the traffic environment every target site is now defending against, which is why a provider's anti-bot handling, not its parsing, decides whether a project on complex sites survives contact with production.
3. What level of compliance and ethics do you need?
This matters to every industry but especially Finance, Healthcare, AI training, Market intelligence, and Public companies. Recent rulings have reshaped the legal posture for public-data extraction: in Meta Platforms v. Bright Data (N.D. Cal., 2024) the court found that Meta's terms of service did not reach Bright Data's logged-out scraping. That was a ruling on those contract terms, not a holding that scraping public data is lawful in general. In parallel, Regulation (EU) 2024/1689, the EU AI Act, introduced data-sourcing transparency obligations that cascade to any buyer whose downstream consumers train AI models on the extracted data: a cross-cutting requirement, not an AI-only one.
The practical buyer checklist has shifted accordingly. Ask vendors for their data-sourcing audit log, their robots.txt handling policy, their response-to-takedown protocol, and how they document data provenance for downstream AI use. GDPR and CCPA practices remain table stakes; case-law-aware sourcing and AI-Act-ready provenance are the new differentiators. A deeper walkthrough lives in the compliance deep-dive.
4. What is the real cost, not just the price per request?
The structural cost drivers in web scraping are not the price-per-request line item. They are proxy infrastructure, engineering response time when websites change, storage and post-processing, and the opportunity cost of decisions delayed by unreliable data. Across in-house operations, proxy infrastructure is consistently the single largest variable cost, roughly a quarter to two-fifths of the in-house cost stack in directional terms, though the exact share varies by website mix and volume. The math is laid out in the real cost analysis.
Expert Insights
The U.S. Bureau of Labor Statistics puts the median annual wage for software developers at $135,980 in May 2025. Price one engineer's day a week against that figure and scraper repair becomes a five-figure annual cost that never appears on a per-request price list.
Consider hidden expenses including engineering hours fixing broken scrapers, preprocessing costs for messy outputs, retrying failed scrapes, and rebuilding pipelines when websites change. The right provider saves money through reduced maintenance burden.
5. Can they guarantee stability when it matters?
Request uptime SLAs (ideally 99.9%+), response times, escalation SLAs, past success rates, and enterprise customer references. Data pipelines are essential to operational frameworks.
Quick Summary
Q: How do you compare web scraping providers without getting lost in feature lists?
A: Work through five checks in order: the use case and the volume behind it, how hard your target sites are to collect from, the sourcing and handling rules you need written down, the full cost stack rather than the per-request price, and the uptime and escalation SLA you can hold a vendor to.
Top 10 Web Scraping Service Companies
Quick Summary
Q: Ten vendors evaluated across managed-service depth, infrastructure scale, compliance posture, and use-case fit. Forage AI leads for fully managed, custom enterprise pipelines.
A:
1. Forage AI – Best for Custom & Fully Managed Web Scraping
Forage AI specializes in managed custom web scraping solutions, automated data pipelines, and AI-powered extraction for complex and dynamic websites. Operating extraction pipelines for 12+ years across 500M+ websites and 10M+ documents, Forage AI emphasizes end-to-end data delivery, managing everything from sourcing to cleaning to enrichment, backed by 100+ data experts and a QA team three times the industry-average size relative to delivery.
Pros:
- AI-powered extraction for complex websites
- Fresh, structured datasets ready for analytics or ML training
- Documented sourcing rules and no data reselling
- Automated change detection and pipeline monitoring
- Enterprise onboarding and long-term support
Cons:
Fully managed, enterprise-grade solution may not suit teams seeking quick, self-service scraping tools. Best for mid-to-large organizations with complex data needs.
2. Bright Data – Best for Large Proxy Infrastructure
Bright Data offers proxy networks and web scraping solutions for enterprises worldwide, with both DIY scraping and managed services.
Pros:
- Extensive proxy pool with vast IP addresses
- Mature ecosystem with comprehensive tools and resources
- Flexible APIs for customized workflows
Cons:
Technical expertise required; platform complexity challenges users with limited skills, especially for large-scale custom scraping.
3. ScrapingBee – Best for Developer-Friendly APIs
ScrapingBee emphasizes an API-first approach with straightforward, efficient solutions for engineering teams and quick integration.
Pros: Simple API, fast integration
Cons: May lack extensive enterprise compliance features
4. IPRoyal – Best for Cost-Effective Proxy & Scraping Needs
IPRoyal offers diverse proxy tools and reliable scraping services at competitive prices, ideal for mid-sized companies needing effective solutions without sacrificing performance.
Pros: Competitive and transparent pricing, diverse proxy types
Cons: Some users find advanced customization options limited compared to higher-end solutions
5. Oxylabs – Best for High-Volume DIY Data Collection
Oxylabs handles extensive data-collection needs, particularly favored by enterprises requiring millions of monthly requests, which is the volume profile most Oxylabs alternatives are measured against.
Pros: High throughput with exceptional reliability, strong infrastructure supporting large-scale requests
Cons: Custom scraping projects may necessitate extra support or additional costs
6. Zyte – Best for Reliability and Mature Technology
Zyte (previously Scrapinghub) offers structured data extraction solutions backed by Smart Proxy Manager, providing strong reliability for complex requirements.
Pros: Proven platform known for reliability and AI-based data extraction features.
Cons: Pricing structures can be complex; requires an engineering team to operate Zyte tools.
7. WebScrapingAPI – Best for Fast Deployment
WebScrapingAPI excels in flexible, quick-deployment experiences with user-friendly API endpoints, ideal for rapid prototyping and small-to-mid-sized enterprises.
Pros: User-friendly, plug-and-play APIs that speed up deployment.
Cons: Limited customization options for complex scraping scenarios.
8. Apify – Best for Workflow Automation
Apify offers comprehensive automation tools with pre-built actors available in a marketplace, ideal for teams needing efficient solutions without starting from scratch.
Pros: Vast marketplace offering various scrapers with seamless workflow integration.
Cons: Custom enterprise tasks may require additional engineering resources.
9. Datahut – Best for On-Demand Custom Datasets
Datahut specializes in clean, pre-packaged datasets for business intelligence and market research with next-day delivery focus.
Pros: Quickly delivered ready-to-use datasets for various business needs.
Cons: Less effective for dynamic data requirements or constant updates.
10. Datarade Providers – Best for Multi-Vendor Discovery
Datarade enables enterprises to access verified data providers with easy vendor comparison by ratings and profiles.
Pros: Efficient vendor evaluation process with detailed ratings and comparisons.
Cons: Data quality and reliability vary significantly across partners, necessitating thorough vetting.
Data Providers Comparison Table
| Provider | Service Type | Strengths | Limitations | Best For |
|---|---|---|---|---|
| Forage AI | Fully Managed, Custom Pipelines | Handles complex websites, AI-powered extraction, structured datasets, agreed handling rules, end-to-end delivery | Not self-serve API; optimized for enterprise scale | AI/ML teams, finance, real estate, healthcare, LLM data pipelines |
| Bright Data | API + Proxy Infrastructure | Massive proxy pool, mature tools ecosystem, flexible APIs | Requires high engineering effort for custom scrapers | Large-scale DIY data collection, enterprise teams |
| ScrapingBee | API for Developers | Simple API, clean docs, great for fast integration | Limited enterprise governance features | Developer teams needing quick scraping integration |
| IPRoyal | Proxy + Budget Scraping | Low-cost proxies, variety of IP types | Limited advanced customization | Mid-size businesses, cost-sensitive scraping |
| Oxylabs | API + Proxy Infrastructure | High throughput, anti-bot strength, and reliable | Custom scraping may require extra support | High-volume scrapers, enterprises |
| Zyte | API + Developer Tools | Mature tech, strong reliability, Smart Proxy Manager | Requires an engineering team; pricing can be complex | Teams building their own scraper logic |
| WebScrapingAPI | Fast-Deploy API | Quick setup, plug-and-play API | Limited customization for very complex sources | Fast prototyping, SMEs |
| Apify | Platform + Prebuilt Scrapers | Huge marketplace, workflow automation | Not ideal for dynamic/very complex websites | E-commerce, automation-heavy teams |
| Datahut | Managed Custom Datasets | Ready-to-use datasets, next-day delivery | Not suited for custom/AI-ready pipelines | BI teams, market research |
| Datarade | Multi-Vendor Marketplace | Easy vendor comparison, wide supplier list | Data quality varies by vendor | Teams evaluating multiple data sources |
Why Choose Forage AI for Web Scraping?
From 12+ years operating extraction pipelines across 500M+ websites and 10M+ documents, Forage AI stands as a premium, fully managed service provider for enterprise data pipelines. Unlike competitors focused on infrastructure like proxies and APIs, Forage AI is positioned for organizations viewing data as a strategic asset.
Three core differentiators:
- End-to-End Ownership: Forage AI manages the entire data pipeline, from navigating anti-bot systems to delivering clean, validated datasets. The operation runs on 100+ data experts and a Multi-Layer Process where every extraction passes automated checks followed by human verification, a 200% QA approach. Clients receive usable data rather than tools.
- Customization Over Commoditization: Forage AI specializes in bespoke solutions for complex, dynamic, large-scale data-extraction challenges where data quality is non-negotiable. Pipelines are designed around each client’s specific data requirements and business rules, with domain expertise across 15+ industries enabling faster identification of relevant data sources and accelerated time-to-launch. It is not a self-service, one-size-fits-all tool.
- Business Outcome Focus: By removing internal maintenance burden, Forage AI enables engineering teams to focus on core product development and provides business teams with reliable, analyst-ready data. The QA team is three times the industry-average size relative to delivery headcount, which is the operational reason client teams can focus on consuming data rather than validating it.
Forage AI is ideal for enterprises seeking a strategic partner to manage data pipelines, prioritizing reliability and agreed handling rules. Its value shows up in total cost of ownership, not just the initial price.
Which Provider Fits Your Industry?
| Industry | What the Industry Needs | Best-Fit Providers | Where Forage AI Excels |
|---|---|---|---|
| Finance & Investment | High accuracy, regulatory rigor, fast refresh cycles, well-structured datasets | Forage AI, Bright Data, Oxylabs | Ideal for niche, multi-source financial and alternative data feeds requiring strict validation and clean, ready-to-use formats |
| Healthcare | Healthcare data sourcing under client-specific handling rules, high-quality structured datasets, entity-level extraction, ongoing public health monitoring | Forage AI, Bright Data, Zyte | Expertise in complex healthcare sources, medical taxonomies, provider directories, insurance metadata for analytics, AI, and regulatory needs |
| E-commerce & Retail | Large-scale product data, price and stock monitoring, catalog coverage across thousands of URLs (Mordor 2026: 19.23% CAGR for price monitoring; 81% of US retailers use automated price scraping) | Forage AI, Zyte, Datahut, Datarade | Best for enterprise-grade catalog automation where millions of SKUs need to stay fresh across global markets |
| AI & Machine Learning | Consistent training datasets, clean structured fields, predictable updates, domain-specific formats | Forage AI, Apify, Bright Data | Delivers high-quality, domain-tuned datasets that reduce preprocessing and improve model performance |
| SaaS & Market Research | Competitor tracking, signal extraction, automated insights pipelines at scale | Forage AI, WebScrapingAPI | Builds managed data pipelines that deliver straight into internal dashboards and analytics systems |
Final Recommendation
Selecting a web scraping provider is a foundational decision for any enterprise depending on data. The right partner strengthens the entire data supply chain by delivering accurate, well-governed, structured data you can trust.
If your organization needs reliable, high-quality pipelines for AI, market intelligence, fintech, or product analytics, Forage AI offers a fully managed, end-to-end approach eliminating the burden of maintaining scrapers, proxies, and internal QA workflows.
“Stop being a data collector. Start being a data consumer.”
If exploring a strategic data partner beyond basic tools, Forage AI’s team can help design a pipeline fitting your industry and operational needs.
FAQs
What is a web scraping service company?
A web scraping service company collects structured data from public websites on your behalf. Instead of building your own scrapers, you get clean, ready-to-use data delivered in needed formats. This removes complexity of handling proxies, errors, and website changes internally.
How do I choose the best web scraping provider for my business?
Start by defining data volume, frequency, freshness, and format needs. Then compare providers based on accuracy, compliance, scalability, and support model. The best partner reliably meets your goals without adding operational overhead.
What’s the difference between API-based and fully managed web scraping services?
API-based tools provide infrastructure but require teams to manage scraping logic and failures. Fully managed services own the entire pipeline from extraction to delivery, so you focus only on using data, not maintaining systems. Enterprises typically prefer the managed approach.
Which web scraping companies are best for enterprise use cases?
Forage AI stands out for enterprises needing custom, end-to-end pipelines rather than tools. The right choice depends on how hands-on your team wants to be. Bright Data, Oxylabs, and Zyte offer strong infrastructure, while Forage AI is the strongest fit for teams that want a fully managed pipeline.
Is Forage AI a web scraping service provider?
Yes, Forage AI is a fully managed enterprise web scraping and data extraction partner. They build custom pipelines handling complex sources, high volumes, and strict handling requirements. You get complete, structured data delivered automatically.
What makes Forage AI different from other web scraping companies?
Forage AI provides fully managed, highly customized pipelines instead of generic APIs or off-the-shelf scrapers. They handle extraction, quality checks, enrichment, and delivery end-to-end. This gives enterprises cleaner data, lower operational burden, and higher reliability.
Is web scraping legal in 2026?
There is no blanket answer, and the US case law is still moving. In Meta Platforms v. Bright Data (N.D. Cal., 2024) the court found that Meta's terms did not reach logged-out scraping, which decided those contract terms rather than establishing that public-data scraping is always permitted. For buyers whose data feeds AI model training, Regulation (EU) 2024/1689, the EU AI Act, adds data-sourcing transparency obligations that flow downstream regardless of where the model is trained.
How much does enterprise web scraping cost?
Enterprise web scraping cost is rarely the per-request price. The real cost stack is proxy infrastructure, engineering response time when websites change, storage and post-processing, QA, and delivery integration. Engineering hours absorbed by pipeline breaks tend to compound past the all-in cost of a managed provider within roughly six months. The full cost analysis walks through the math.
Sai is a data infrastructure enthusiast who has spent the past two to three years following the AI space closely, from the infrastructure layer to the fast-growing world of data for AI. He is genuinely curious about how modern data pipelines get built and where the data industry is heading, and he writes insightful pieces on the core topics that shape this niche.